- Infrastructure
- Iceberg Setup Requirements
Infrastructure
Iceberg Setup Requirements
Setting up Iceberg as your offline store.
Chalk’s feature platform enables machine learning teams to focus on building the unique products and models that make their business stand out. Chalk provides a feature store so that you can deploy production machine learning pipelines for real-time data in minutes.
Chalk is both a framework and a platform — developers can write code using familiar Python packages, and deploy their feature and data pipeline definitions to Chalk’s platform. In the Customer Cloud deployment, Chalk runs and administers its platform on the customer’s cloud account. Chalk’s managed infrastructure then executes the customer-defined pipelines to compute feature data for machine learning applications. Chalk then serves this data back to customer applications for online inference and to customer data teams for training set generation.
Configuring an Iceberg Offline Store
The Iceberg offline store leverages AWS Glue Catalog, a fully managed metadata catalog that simplifies data discovery and schema management for data lakes. This option gives you direct control over your AWS infrastructure and data storage, unlike managed solutions like Snowflake or Databricks where compute and storage are abstracted away. Your data remains in your S3 buckets without vendor lock-in.
Required Information
To set up the Iceberg offline store, you will need:
- S3 bucket name: The S3 bucket where your offline store data will be written. You may reuse an existing bucket or create a new one specifically for offline store usage. This bucket should be in the same AWS region in which Chalk is deployed.
Step 1: AWS Permissions
You’ll need to grant the following IAM permissions to the Chalk execution role. Note that many of these are base permissions you may have already configured. The key addition is Glue access for catalog operations, including table creation, schema evolution, and metadata management:
{
    "Statement": [
        {
            "Action": [
                "s3:*",
                "dynamodb:*",
                "secretsmanager:*",
                "sqs:*",
                "sts:AssumeRole",
                "glue:*"
            ],
            "Effect": "Allow",
            "Resource": "*"
        }
    ]
}Step 2: Creating the database in Glue Catalog
Before Chalk can use Iceberg for your offline store, you must create an AWS Glue database for the offline store that will serve as the metadata store for your Iceberg tables. You can create the database in your default catalog for the region in which Chalk is deployed.
You may name the database whatever you like, although Chalk recommends a name such as “offline_store”. Note the name down, as you will need it along with the bucket name above when configuring the offline store.
Step 3: Creating and activating the offline store connection
Once you have your S3 bucket and Glue database set up, you can configure the connection in the Chalk dashboard:
- In the dashboard, navigate to Integrations → Offline Store.
- Click New Connection.
- Select Iceberg (Glue + S3) as the provider.
- Fill in the following fields:
- Connection Name: A name to identify this connection (e.g.
Iceberg Offline Store) - S3 Bucket Name: The name of the S3 bucket from the Required Information section above
- Glue Database Name: The name of the Glue database you created in Step 2
- Connection Name: A name to identify this connection (e.g.
- Optionally, click Test Connection to verify that Chalk can reach your S3 bucket and Glue catalog.
- Click Create Connection.
After creating the connection, you’ll be returned to the offline store connections list. Click Activate on your new connection to make it the active offline store for this environment.
Step 4: Configure AWS Glue optimization policies
AWS Glue provides managed optimizers for Iceberg:
- Compaction combines small data files into larger files to reduce metadata overhead and improve read and write performance.
- Snapshot retention expires old snapshots and can remove their associated data and metadata files.
- Orphan file deletion removes files that are no longer referenced by Iceberg table metadata.
These can be turned on at the catalog level or at the table level from within your AWS console.
Once a catalog-level policy is turned on, all tables created after that point will inherit the policy, and all existing tables will inherit the policy as soon as they’re updated. Chalk’s iceberg write operations all count as updates. But, any table-level setting (including disabling optimizations) will always override catalog-wide policies.
Recommended configuration
We recommend that you enable compaction at a minimum.
- Iceberg tables accumulate metadata with every write, and this will degrade read and write performance over time.
- Compaction is particularly helpful if your workloads result in many small writes — which correspond to more datafiles and faster metadata file accumulation.
Many customers also find it valuable to enable a snapshot retention policy and orphan file deletion, but this decision should be based on your own data retention needs.
- You can set snapshot retention to preserve the recovery and time-travel window your organization requires. Expired snapshots can no longer be queried, and enabling cleanup of expired files makes the associated file deletion permanent unless separately protected by storage recovery controls.
- Enabling orphan file deletion means that failed or interrupted writes do not leave unused files indefinitely. Use a retention period longer than the longest expected write or maintenance operation so an in-progress file is not mistaken for an orphan. Each table must have a unique, non-overlapping S3 location; otherwise, cleanup for one table can delete files belonging to another table or data source.
Review AWS’s optimizer considerations and limitations before enabling file deletion. The Apache Iceberg maintenance guidance provides additional detail about safe orphan-file retention for concurrent writers.
Viewing your current optimization policies within Chalk
While all policies must be configured within AWS Glue, Chalk surfaces your current settings in the Offline store connection page.
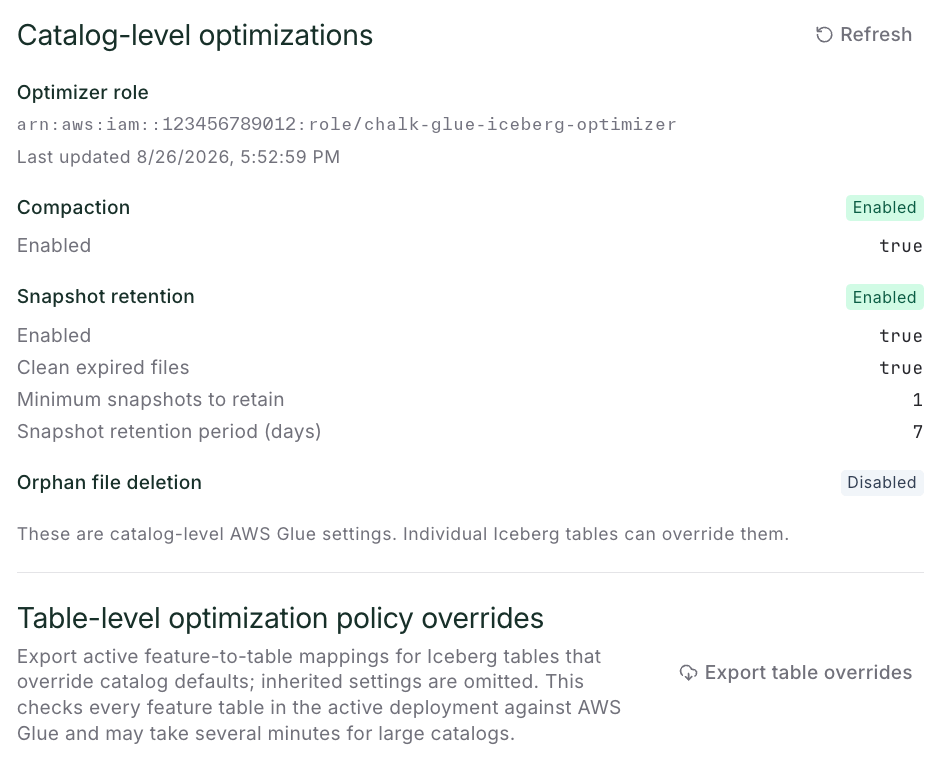
The catalog-level settings are automatically displayed, but you can also export a summary of any tables that override the catalog defaults.
This summary checks the active deployment’s feature tables and the query_log table. It
exports only policies whose AWS Glue configuration source is the table itself; tables that inherit every catalog
default are omitted. Large catalogs can take several minutes to inspect. The CSV contains:
feature_fqn,table_name,compaction_settings,retention_settings,orphan_file_deletion_settingsQuerying against the Iceberg Offline Store
The Iceberg offline store can be accessed using the Chalk SQL Interface. In the dashboard, you can
navigate to the SQL Explorer and run SQL queries directly against the historical feature value
tables and the query values tables that Chalk maintains in the offline store. In the SDK,
you can use the ChalkGRPCClient.run_sql() method to execute the same SQL queries programmatically.