Getting Started
Your first time with Chalk
Introduction
Chalk’s platform is a powerful tool that allows data engineers and data scientists to collaborate efficiently and effectively.
In this project we’ll create features related to Usersand their credit scores. We’ll combine data from an
API and a database to help us decide whether we should issue
new loans.
You will learn how to create a new Chalk project, create features and resolvers, deploy them to the Chalk environment, and query the environment using the Chalk CLI and a Jupyter Notebook.
This tutorial will take about 45 minutes to complete end-to-end.
Installing the Required Software
- If you don’t have a favorite IDE, install VS Code by visiting the download site and running the appropriate installer.
- You’ll also want to install
the
codeCLI command. - Install the Chalk CLI by running
$ curl -s -L https://api.chalk.ai/install.sh | shCreating your Chalk project
Now that all of your software is installed, let’s create a Chalk project where you will add your features and resolvers.
- Log in by typing
chalk login. If you’re using a dedicated environment, make sure you use the--api-hostflag. Typeywhen prompted and log in through the browser. - Create a folder called
chalk-tutorial, and runchalk initfrom inside it.
$ mkdir chalk-tutorial
$ cd chalk-tutorial
$ chalk init
chalk init takes the project name from your login. If you
have access to more than one project, it asks you to choose one.
It also asks whether you use a coding agent such as Claude Code
or Codex. Choose one to have chalk init set it up with
Chalk-specific instructions, or choose Skip.
3. chalk init creates the files for your project, including:
chalk.yaml, which contains configuration information about your project.chalkignore, which tells the Chalk CLI which files to ignore when deploying to your Chalk environment, and works like a.gitignorefilepyproject.toml, which lists the Python libraries your project depends on
chalk init manages these libraries with uv, and
offers to install uv if you don’t have it. It then installs chalkpy and chalkcompute into a
virtual environment in .venv. If chalk init installs uv for you, open a new
terminal and return to chalk-tutorial before you continue. The Setup Guide describes
everything chalk init does.
Now you’re ready to deploy code and query the environment!
Set up your virtual environment
chalk init created a virtual environment
so that you can download and use Python libraries
in your Chalk project.
- Run the following command from inside your Chalk project
to activate your virtual environment.
When you want to deactivate your virtual environment,
type
deactivate.
$ source .venv/bin/activate- We’ll use a few more libraries for this tutorial. Add them
with
uv add, which lists them inpyproject.tomland installs them in your virtual environment. Feel free to add more libraries later.
$ uv add pydantic requests- Check that the libraries are installed by importing
requestsin Python. If there’s no error message, it worked. Exit by typingexit()and hitting enter.
$ python
>>> import requests
>>> exit()Use Curl and Jupyter to call APIs.
Now that all the software is installed and ready to use, you’re ready to start integrating an API.
- First, lets test the API we’re going to use. Run this command to hit the API from your command line. Here we’re asking “give me the credit score for user 12” and the API gives us back a JSON object with a credit score.
$ curl https://credit-report.chalk.dev/rutter_score/12
{"score":98}
Now you should try to hit this API from Python using a Jupyter Notebook.
- Open VS Code, and create a new file
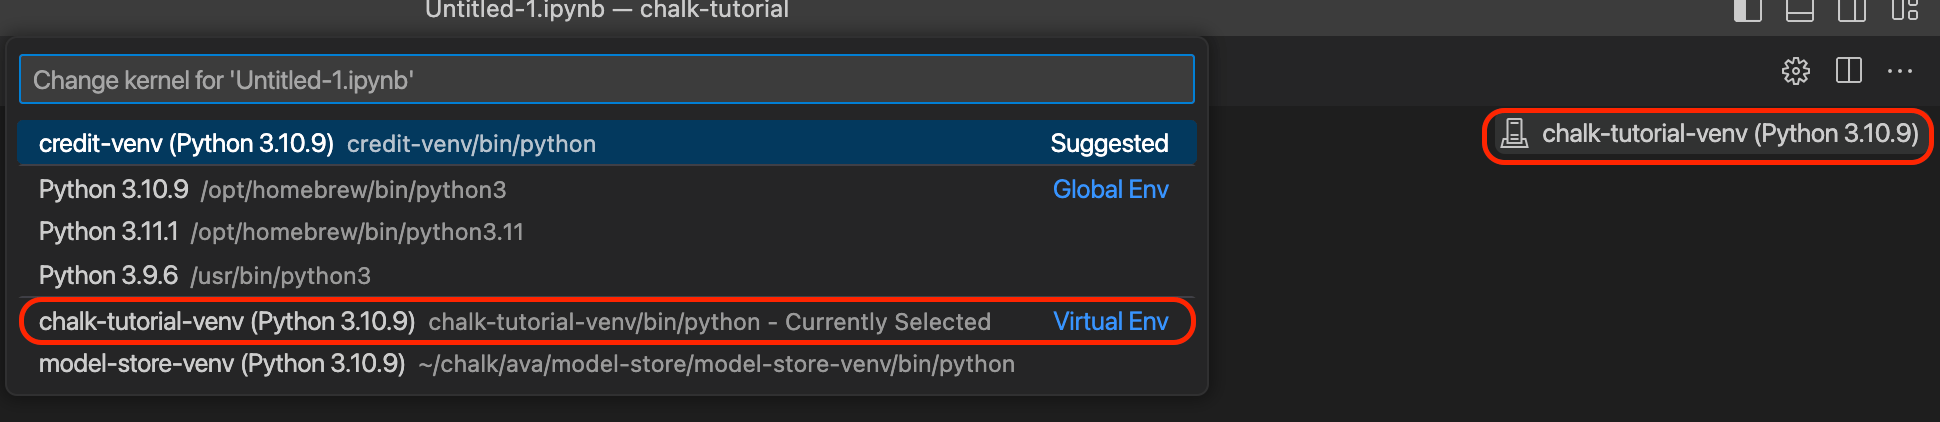
File -> New File. SelectJupyter Notebook. - Jupyter will probably ask you which interpreter to use.
If it does, select the virtual environment that
chalk initcreated (.venv). - If not, you can select it manually.
- Finally, let’s query the API from Jupyter. Enter the following
code and run it with
shift+enter.
import requests
requests.get(
    "https://credit-report.chalk.dev/rutter_score/12"
).json()["score"]
If you see 98, congratulations! You’re all setup and ready to start developing your Chalk project.
Building a Chalk project
With all the pre-requisites completed, let’s jump right into building your Chalk project.
Creating your first Chalk feature
We’ll create a feature called User with a “Rutter score”
property. The resolver will call the “Rutter” API we tested
earlier, passing the User ID, and return the score.
After you deploy the feature, you will test it in
Jupyter.
- Create a
credit.pyfile and copy in the feature and resolver definitions below:
import requests
from chalk.features import online, features, Features

@features
class User:
    id: str
    credit_score: int

@online
def get_credit_score(
    id: User.id,
) -> Features[User.credit_score]:
    return requests.get(
        f"https://credit-report.chalk.dev/rutter_score/{id}"
).json()["score"]- Deploy your code. Pass the
--branchflag with a name so that you don’t affect the “actual” environment
chalk apply --branch test- Now lets query for your feature from your Jupyter Notebook. Enter and execute the following code in your notebook.
from credit import User
from chalk.client import ChalkClient
ChalkClient().query(
   input={User.id: 'u_F6zY0tE4w8'},
   output=[User.credit_score],
   branch="test"
)
You can also query for this feature in your terminal:
$ chalk query --in user.id=u_F6zY0tE4w8 \
              --out user.credit_score \
              --branch test
Congratulations! You’ve written your first Chalk feature, connected it to an external API, and queried it from a Jupyter Notebook. This is a big achievement!
Adding a database to Chalk
We have a database containing more information about users, and it would be good to combine that information together on our user feature.
- If you have psql
or similar tool installed, you can preview the database from the command line.
When prompted, the password is
postgres.
psql -U postgres -p 5432 -h 35.188.7.252 -d postgres
postgres=> select * from users limit 10;
Notice that we know name, surname, email, birthday, and
is_fraud, a flag that tells us whether we know this user
has committed fraud in the past.
- To use this in your Chalk project, we’ll add the database through the UI. Navigate to your environment, and find “Data Sources” on the left hand navigation.
- If you see the database already, great, you can skip the next step of adding the database. Otherwise, continue.
- Click
Add a Data Sourceand choosePostgreSQL. - Fill out the fields as shown here. The password is
postgres.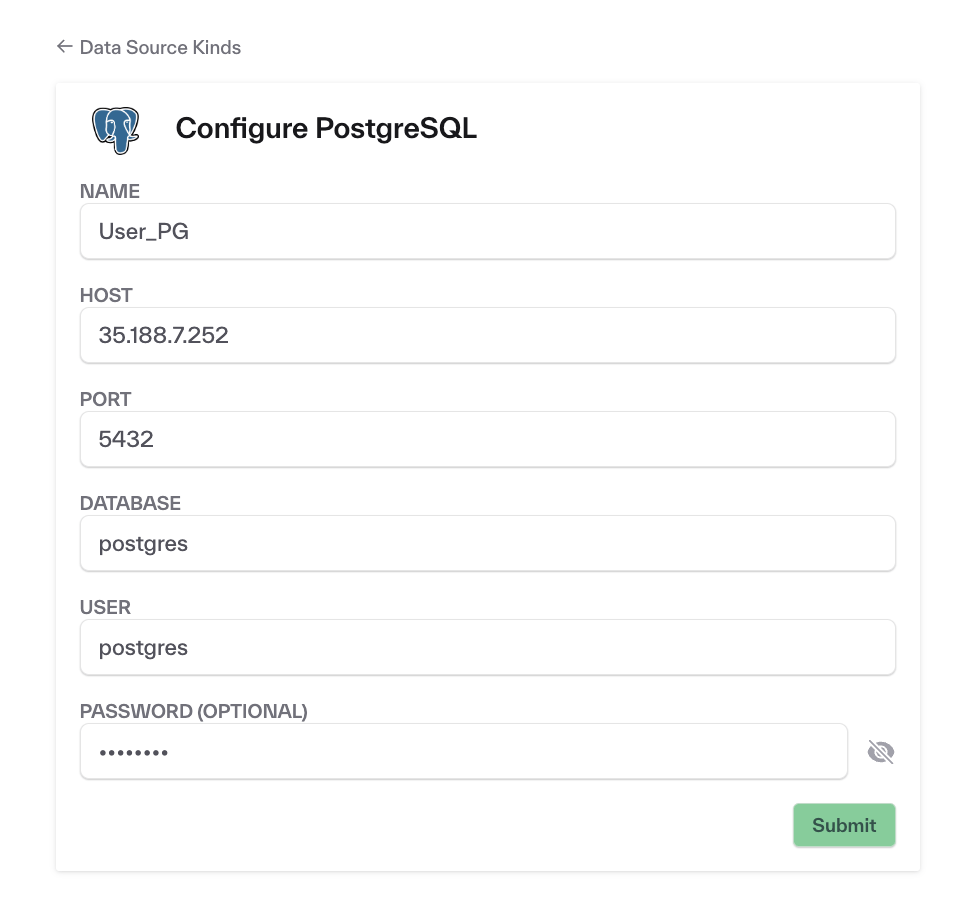
Write a resolver that resolves a database
- Add the fields from the database to the
Userfeature class you created before. The propertiesname,surname, andemailare strings. Birthday is a date, andis_fraudis a boolean. (Hint: you may have to addfrom datetime import dateto your credit.py file) - Add the datasource to your Python context. Add the below
code to your
credit.pyfile. This tells Python about your datasource.
from chalk.sql import PostgreSQLSource
user_pg = PostgreSQLSource(name="User_PG")- You can use a SQL File Resolver
to pull this information. Create a new file called
users.chalk.sqland copy the below contents:
-- type: online
-- resolves: user
-- source: postgres
-- count: 1
select name, surname, email, birthday, is_fraud from users where id=${user.id}- After deploying (remember to use
--branchwith the name you specified, for example “test”), query your feature. SupplyingUseras the output tells Chalk to give you back ALL the features ofUser.
res = client.query(
    input={User.id: 'u_F6zY0tE4w8'},
    output=[User],
    branch="test"
)
You can also query for this feature in your terminal:
$ chalk query --in user.id=u_F6zY0tE4w8 \
              --out user \
              --deployment test